
MiniMax H3 Two Person Video Workflow: Keep Roles, Dialogue, and Motion Clear
AI Overview
Can MiniMax H3 generate two people in one video?
Yes. H3 can stage multiple characters, but each person needs a distinct identity, position, action, and speaking role. A short scene with one interaction is more reliable than a crowded prompt with several simultaneous movements.
How do you stop two characters from swapping identities?
Assign stable labels such as Subject 1 and Subject 2, give each a unique wardrobe and screen position, and repeat only the traits that must persist. Use separate reference images when identity accuracy matters.
How should two-person dialogue be written in MiniMax H3?
Give speakers stable IDs such as S1 and S2, name who speaks before every line, and place only the exact spoken words inside the dialogue tag. Specify that the listener's mouth stays closed.
Which H3 mode is best for a dual-character scene?
Use text or first-frame mode for a simple invented scene, first-and-last-frame mode for one controlled transition, and full-reference mode when separate images, motion, or voice assets must define the two people.
Choose the Right H3 Mode for Two People
Let the hardest constraint choose the input mode
A MiniMax H3 two person video workflow begins before prompt writing. Decide what must be controlled. Text-to-audio-video is enough when both characters can be invented. One first frame helps when the opening composition, wardrobe, and relative positions already matter. First-and-last-frame mode is useful when a single interaction must land on a known ending, such as one person transferring a case to another.
Full-reference mode is the better fit when Character A and Character B come from different identity images, when a separate video supplies body movement, or when voice references matter. MiniMax documents up to nine reference images, three videos, and three audio clips, with 12 reference files in total. Reference audio cannot be the only input; it must accompany an image or video. Do not mix the frame-control and full-reference jobs into one request.
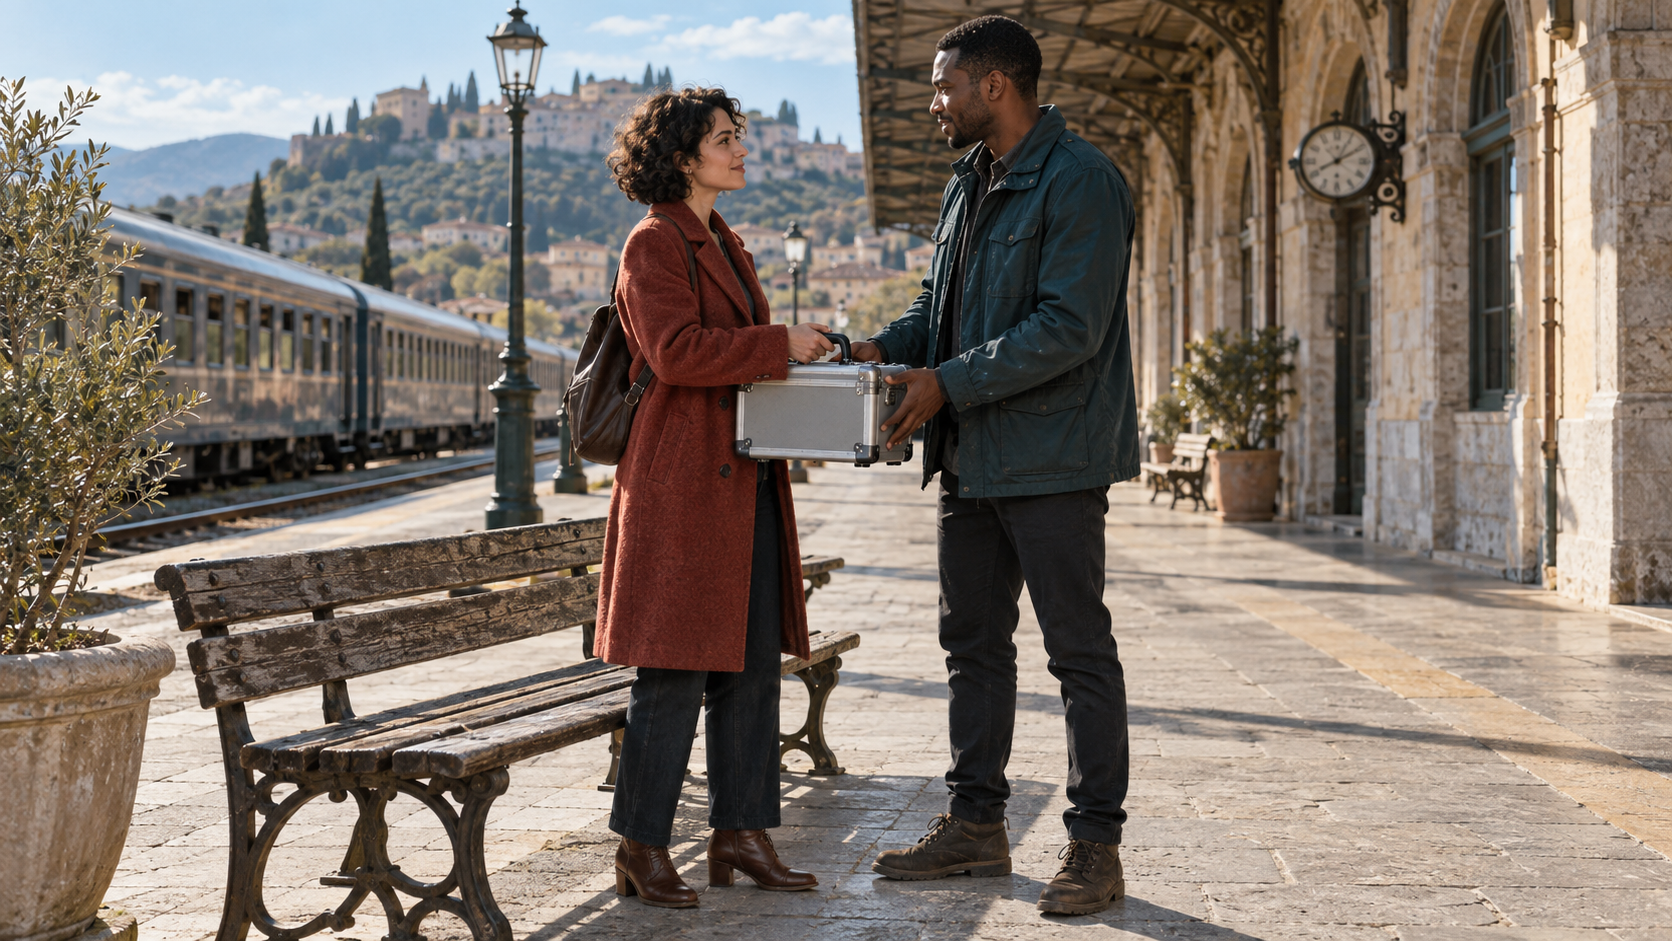
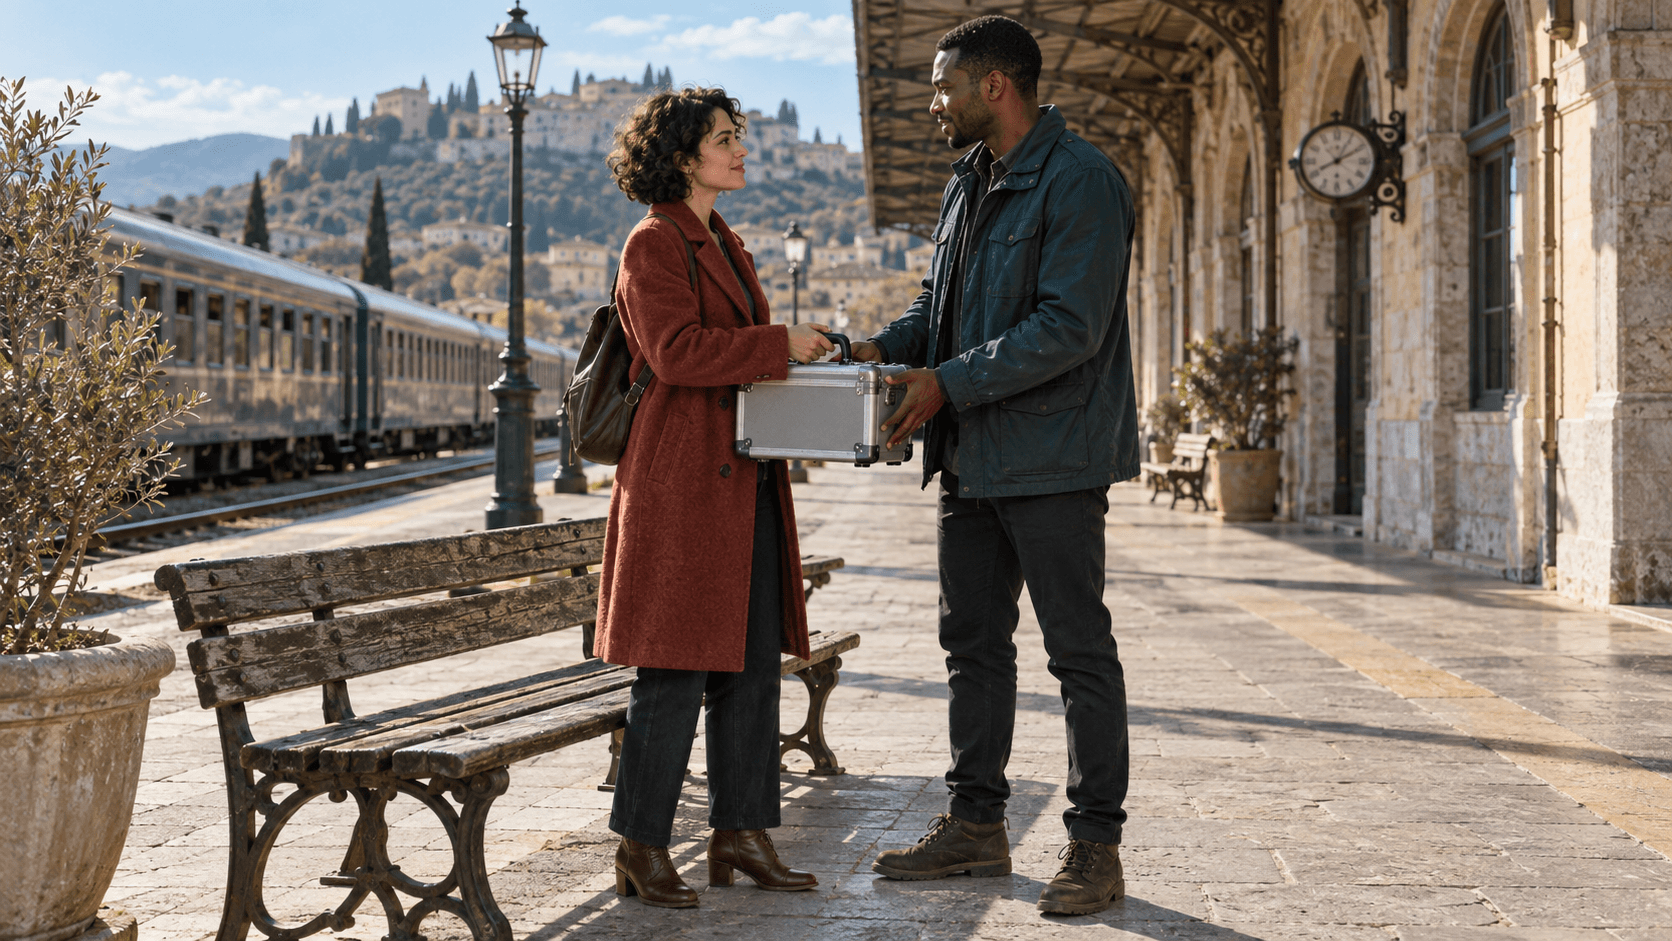
Illustrative generated reference frame: two distinct coats, separate silhouettes, a fixed platform, and one shared prop create readable continuity anchors.
Use duration as an action budget. H3 supports 4–15 seconds, but 15 seconds is not permission to pack in more plot. Give two people one causal beat: approach, exchange, and settle; question, answer, and reaction; or enter, notice, and leave. If the scene needs a second location or another major action, make a new clip and connect it with a resumable multishot workflow.
Define Subject 1 and Subject 2
Create a compact identity and blocking card
Write the two characters as separate production records before writing the timeline. Each card needs a visible identity, wardrobe, initial position, prop ownership, movement limit, speaker ID, and reference source. Differences should be easy to see at a glance; “two people in dark jackets” invites ambiguity.
| Control | Subject 1 | Subject 2 |
|---|---|---|
| Identity | Woman, early 30s, short dark curls | Man, mid-30s, close-cropped hair |
| Wardrobe | Rust-red wool coat, brown boots | Deep teal field jacket, dark boots |
| Start position | Screen left, beside bench | Screen right, near station wall |
| Prop state | Holds case handle | Supports case body |
| Speaker ID | S1 | S2 |
| Motion limit | One step forward, releases handle | Receives case, steps back |
In full-reference mode, define what each asset contributes. A subject label represents reusable visible content, while Picture, Video, and Audio labels identify source media or structural references. Do not call the entire first image Subject 1 if it contains two people and a location. State that Subject 1 is the woman from Picture 1 and Subject 2 is the man from Picture 2; define the platform separately only if it must be actively reused.
subject_definitions:
<Subject 1> is the woman from <Picture 1>, preserving her short dark curls, rust-red coat, face, and brown boots.
<Subject 2> is the man from <Picture 2>, preserving his close-cropped hair, deep teal jacket, face, and dark boots.
<Subject 3> is the small silver equipment case shown in <Picture 3>, preserving its size, handle, latches, and brushed-metal finish.
Avoid re-describing either face differently in later shots. Stable labels reduce competition between adjectives and references. For scene anchors that must survive viewpoint changes, the MiniMax H3 environment consistency guide shows how to name architecture, light direction, furniture, and background objects without turning the prompt into a catalog.
Block the Interaction and Prop Handoff
Describe state changes, not only intentions
“They exchange the case naturally” hides the hardest frames. Write the object state in playback order: Subject 1 owns the handle; Subject 2 places both hands under the case; both briefly support it; Subject 1 opens her fingers and withdraws; Subject 2 steps back with the case; both settle. The model then has an observable path rather than a vague social action.
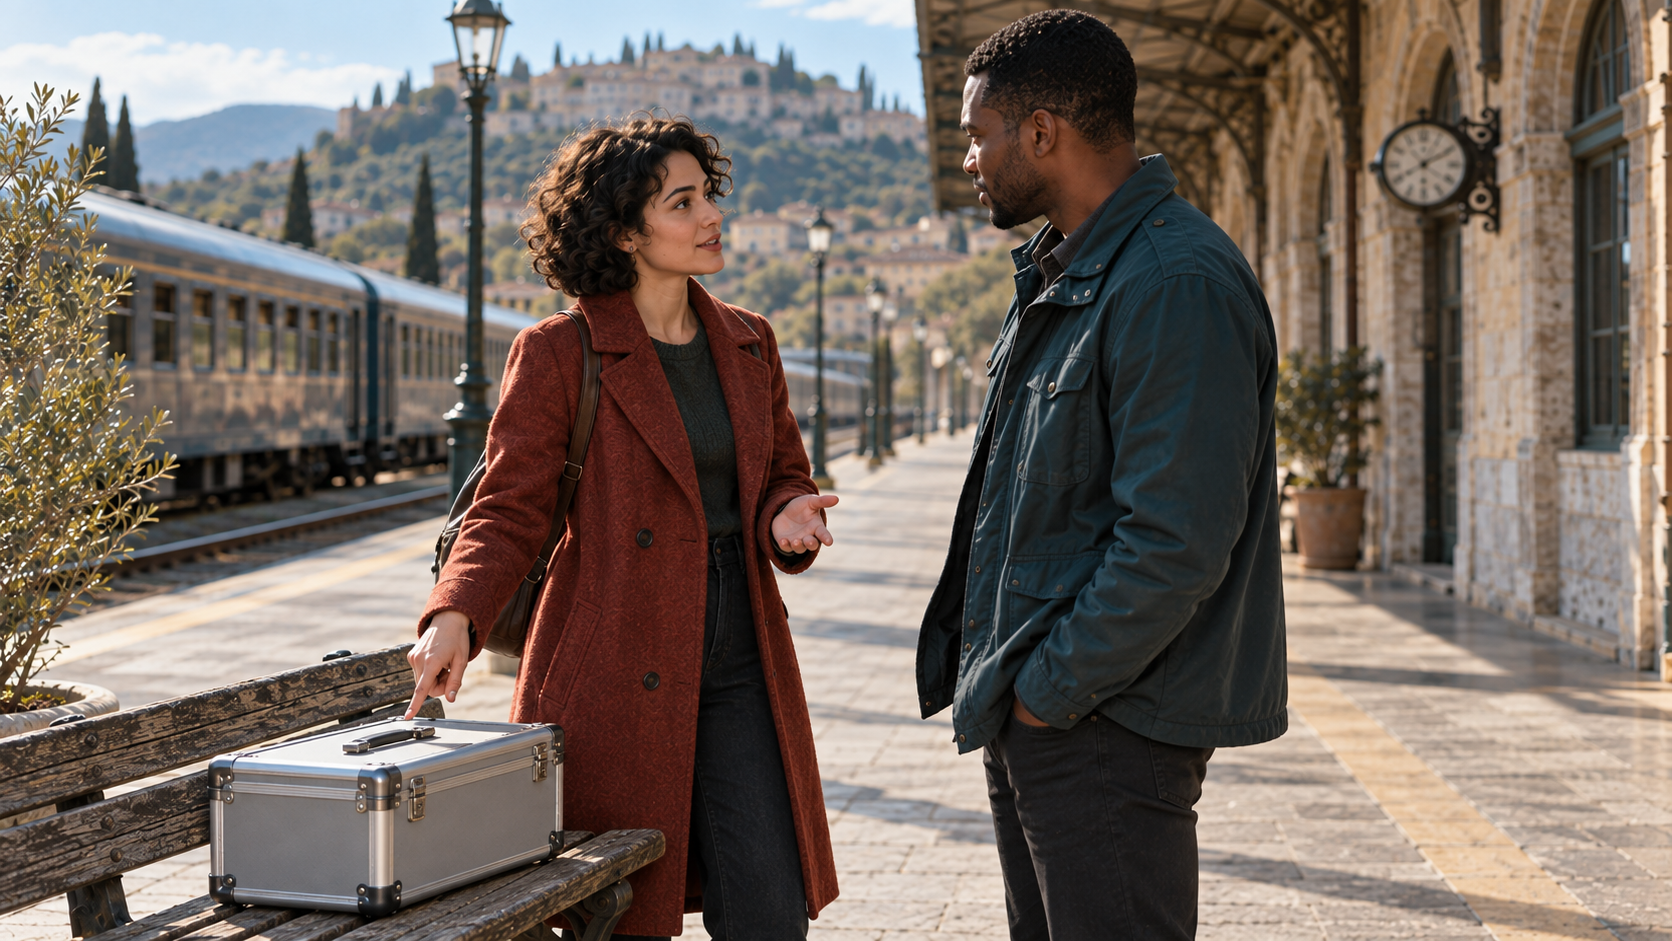
Illustrative generated blocking frame: the speaker owns the gesture, the listener has a clear eyeline, and the case rests in a stable location before the handoff.
Keep spatial language consistent. “Screen left” and “screen right” are camera-relative; “near the tracks” and “near the station wall” survive a reverse angle better. When a cut changes orientation, re-establish both people before the next action. Use one camera move at a time—such as a slow push toward the pair—rather than combining an arc, zoom, pan, and handheld shake.
Hands fail when both people reach through one another or the prompt skips a contact phase. Give the case enough size for two readable grips, prevent either body from crossing the other, and let the exchange occupy several seconds. A clean ending matters: identify who owns the case, where each person stands, where they look, and whether either mouth is moving.
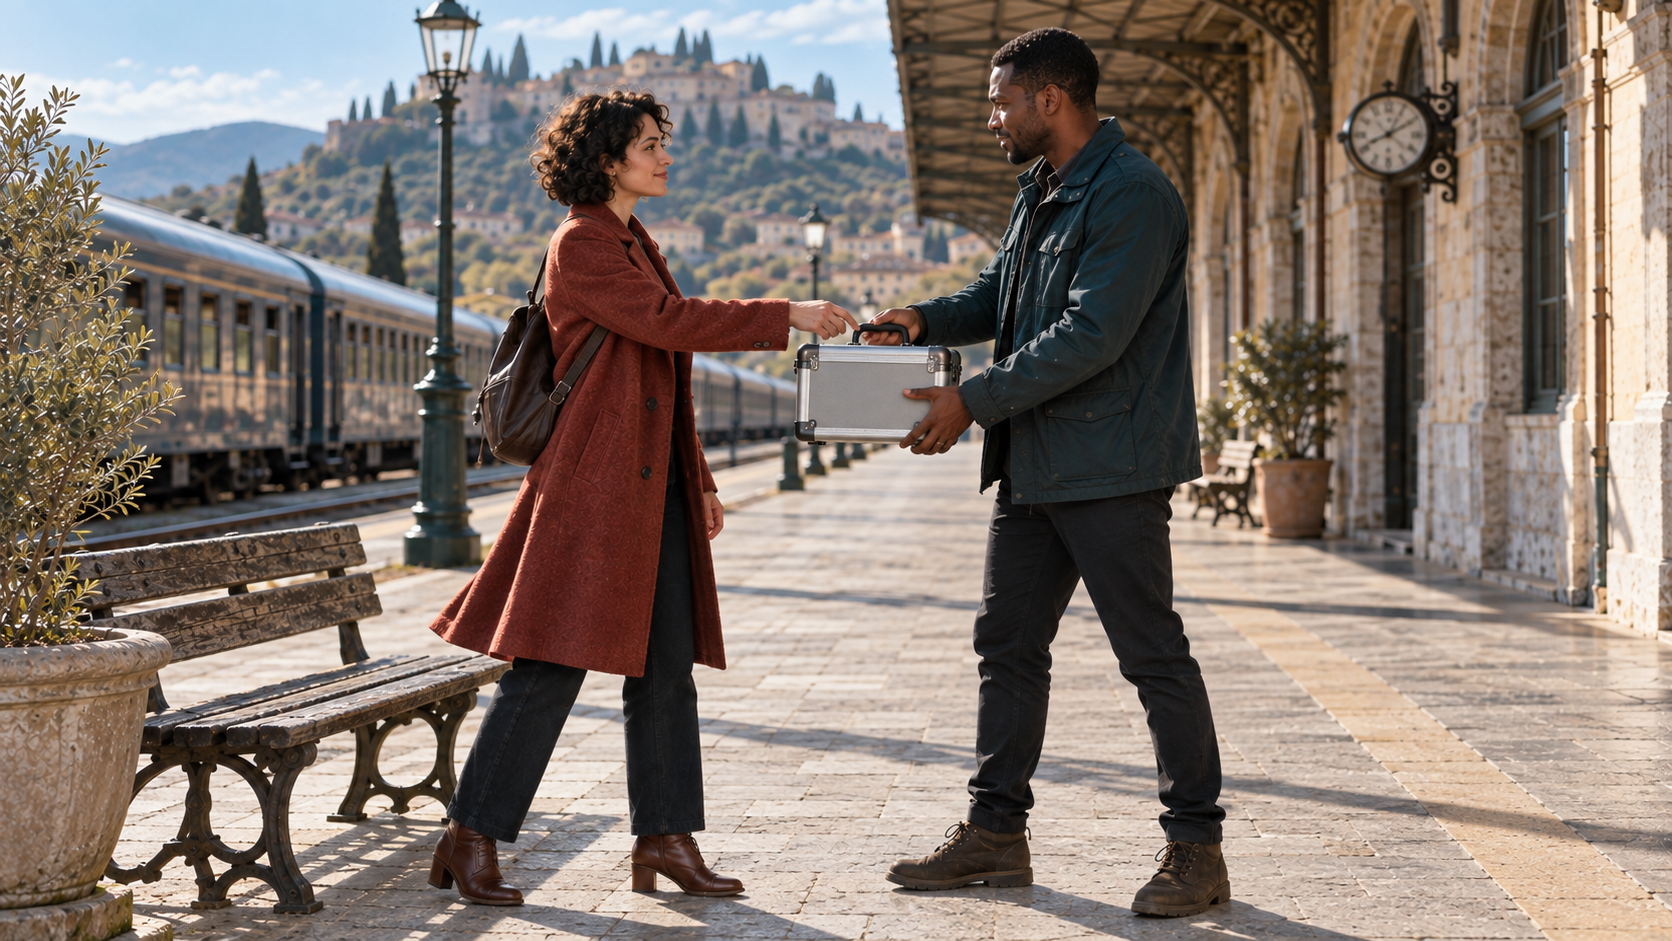
Illustrative generated action frame: inspect hand separation, prop geometry, coat continuity, and the absence of an extra arm during shared contact.
Control Two-Speaker Dialogue and Sound
Assign every line and every listening beat
MiniMax's official base guide uses stable speaker IDs such as S1 and S2. Put the identifying phrase, speaker ID, delivery, and action outside the dialogue tag; keep only the language tag and exact spoken content inside it. When the two speak together, a compound ID such as S1,S2 is supported, but overlapping dialogue is a harder first test than alternating lines.
The woman in the rust-red coat (S1) looks at the case and says quietly: <d>[English] Keep this with you until the next stop.</d> Subject 2 listens and his lips remain closed.
The man in the teal jacket (S2) receives the case, meets her eyeline, and replies: <d>[English] I understand.</d> Subject 1 listens and her lips remain closed.
Use short lines that fit the visible shot. State when speech ends, when the jaw closes, and when the listener reacts. Keep platform ambience, footsteps, case-latch clicks, and cloth movement in the overall soundscape rather than repeating them as dialogue. Put audience-only music in the non-diegetic music field. If a voiceover belongs off-screen, explicitly call it an off-screen voiceover and keep the on-screen character's lips closed.
Actual Seedance output, not a MiniMax H3 result: use a controlled single-speaker clip as the mouth, timing, and room-tone baseline before evaluating a harder two-person exchange.
For recurring voices across several clips, the Seedance voice consistency guide provides a listening pass for timbre, pace, loudness, room tone, and speaker-to-speaker separation.
Build a Three-Shot Continuity Plan
Make every cut inherit a locked state
Three short shots are enough for many two-person scenes. Shot 1 establishes both subjects, the platform, and initial case ownership. Shot 2 moves closer for the handoff and one line from each speaker. Shot 3 confirms the new prop owner and gives both characters a quiet reaction. Give each shot a start state, action, camera behavior, sound, and locked end state.
The end of Shot 1 must equal the beginning of Shot 2. If the case is on the bench at the cut, it cannot appear in Subject 2's hands in the next first frame without a visible pickup. If Subject 1 stands trackside, do not reverse her to the station wall unless the cut and camera orientation explain it. The MiniMax H3 multi-keyframe workflow shows how to assign ordered frames to a master timeline without treating them as a vertical storyboard collage.
H3's base guide allows precise cut times after Shot 1. Use them only when they help, and keep intervals continuous. A practical 12-second plan is 0–4 seconds for establishment, 4–9 seconds for the exchange, and 9–12 seconds for the ending hold. The last two seconds should not introduce a fresh action.
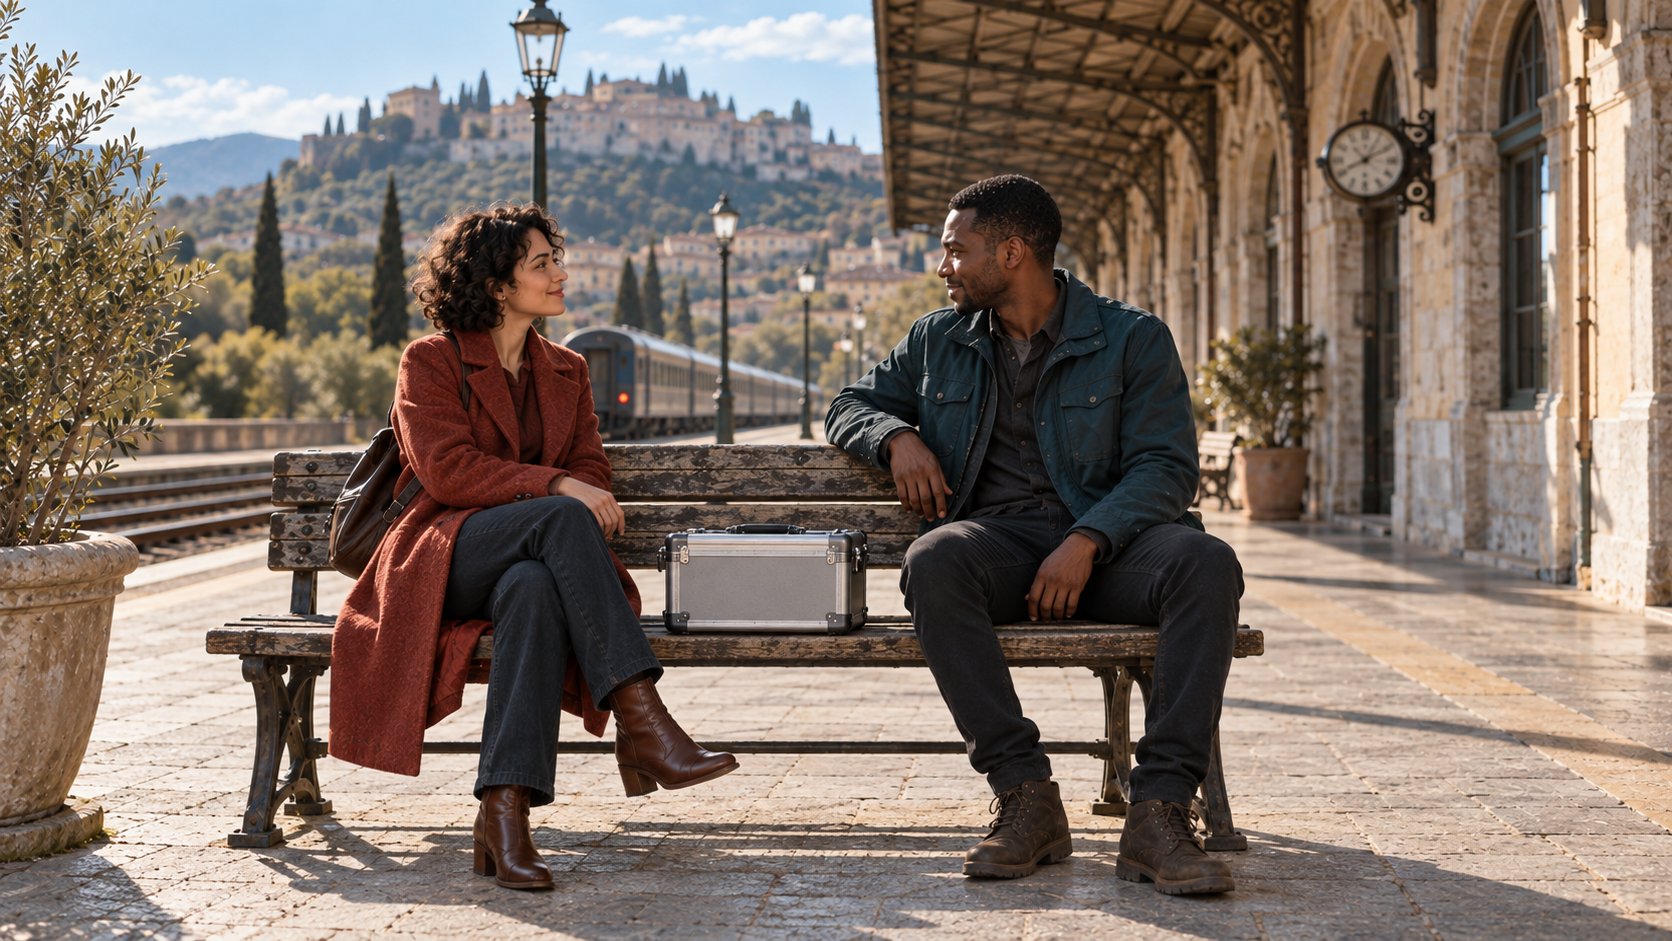
Illustrative generated ending frame: the same faces, coats, bench, station, case, and light make continuity drift easy to detect.
Review Failures and Rerun the Smallest Part
Match each visible failure to one prompt change
Review the complete video at normal speed, then inspect the handoff and dialogue at half speed. If identities swap, strengthen the subject-to-reference mapping and simplify the cut. If faces merge in a wide shot, increase subject separation or move the dialogue to a medium two-shot; the distant-face repair guide covers framing and reference choices for that problem.
| Failure | Likely cause | Smallest useful change |
|---|---|---|
| Characters swap roles | Similar wardrobe or ambiguous labels | Restore distinct labels, clothes, positions, and speaker IDs |
| Both mouths move | Listener behavior unspecified | Add “listens, lips remain closed” after each line |
| Extra arm appears | Handoff skips a contact state | Expand the shared-support and release phases |
| Prop changes shape | Too many actions or weak prop definition | Lock dimensions, handle, finish, and final owner |
| Eyelines break after cut | Positions are not re-established | Restate both positions and gaze at the new angle |
| Environment resets | Scene anchors were implicit | Repeat platform, bench, train, light direction, and time |
Do not regenerate a good establishment because one handoff frame fails. Save the accepted character references, prompt version, seed or task record when available, output, and failure note. Then rerun the smallest shot with one corrective change. Seedance Agent can organize those references, compare candidates, keep the approval state, and route only the failed segment through a reference-to-video workflow.
Conclusion
A reliable MiniMax H3 two person video workflow uses the right input mode, two unmistakable subject records, stable S1 and S2 speaker IDs, one causal interaction, explicit prop-state changes, and a cut plan whose end states match the next openings. Review identity, mouth ownership, hands, eyelines, prop geometry, environment, and sound separately, then rerun only the failed beat. To keep references, shots, approvals, and targeted revisions together, build the two-character sequence with Seedance Agent.
Ready to try it yourself?
Put the steps from this guide into practice with Seedance and turn prompts or images into polished videos in minutes.
Free credits on signup. Plans from $20/month.
Related Articles
More posts in the same locale you may want to read next.
Seedance App Preview Video Generator 2026: Create App Store and Product Launch Clips
Use Seedance to turn app screenshots, feature copy, and launch goals into App Store previews, Google Play promo videos, and product launch clips.
Read article
Socialive Catalyst Early Access Guide: Prepare a Useful First Pilot
Learn who can access Socialive Catalyst, what the early beta includes, what to prepare for a demo, and how to test one branded enterprise video workflow.
Read article
FramePack Torch CUDA Not Enabled: Diagnose and Fix the Right Environment
Fix FramePack when Torch has no CUDA support by checking the exact Python runtime, replacing a CPU-only wheel, handling driver or RTX compatibility, and proving the repair.
Read article