
MiniMax H3 Continuous Talking Avatar Workflow: Keep One Face and Voice Across Clips

AI Overview
Can MiniMax H3 make one continuous talking-avatar video?
Yes, but a long result should be planned as several approved clips rather than one indefinite generation. H3 outputs 4–15 seconds, so divide the script at natural pauses and join segments that share the same face, voice, framing, and room tone.
How do you keep the same avatar identity in every segment?
Use one clean identity reference, repeat the same visible traits, assign one stable speaker ID such as S1, and begin each continuation from an approved neutral boundary frame. Change only the dialogue and the smallest necessary gesture.
What makes talking-avatar cuts look seamless?
End each segment after a complete sentence with a closed mouth, steady eyeline, settled hands, and a short room-tone tail. Start the next segment from that same state, then hide the join under a natural pause or restrained cutaway.
How do you prevent lip sync from drifting?
Keep each spoken block short enough for one breath, write exact dialogue inside the <d> tag, and avoid competing face or camera motion. Review the mouth at normal speed and frame by frame before approving the segment.
Plan a Continuous Avatar as Short Approved Segments
Build the master from breath-sized clips
A MiniMax H3 continuous talking avatar workflow is a production plan, not a request for limitless duration. The official H3 tooling accepts integer durations from 4 through 15 seconds. Treat that ceiling as a creative constraint: each clip should contain one complete idea, one modest gesture, and one clean ending state. A 45-second explanation might become four segments of 10–13 seconds rather than three clips forced to the limit.
Mark the script before generating anything. Good breakpoints follow punctuation, a breath, or a change in topic. Bad breakpoints split a name, number, or emotionally connected phrase. Read every segment aloud with a timer, then reserve roughly one second for the opening settle and the final hold. If the spoken line already consumes the whole duration, shorten the wording rather than asking the model to rush.
| Segment | Spoken job | Target action | Required end state |
|---|---|---|---|
| A | Introduce the topic | Small open-hand gesture | Mouth closed, hands lowering |
| B | Explain the key point | One restrained index gesture | Same eyeline, hands on desk |
| C | Give the example | Brief nod, no camera move | Neutral expression and room tone |
| D | Deliver the CTA | Slight lean, then settle | Two-beat hold for editing |
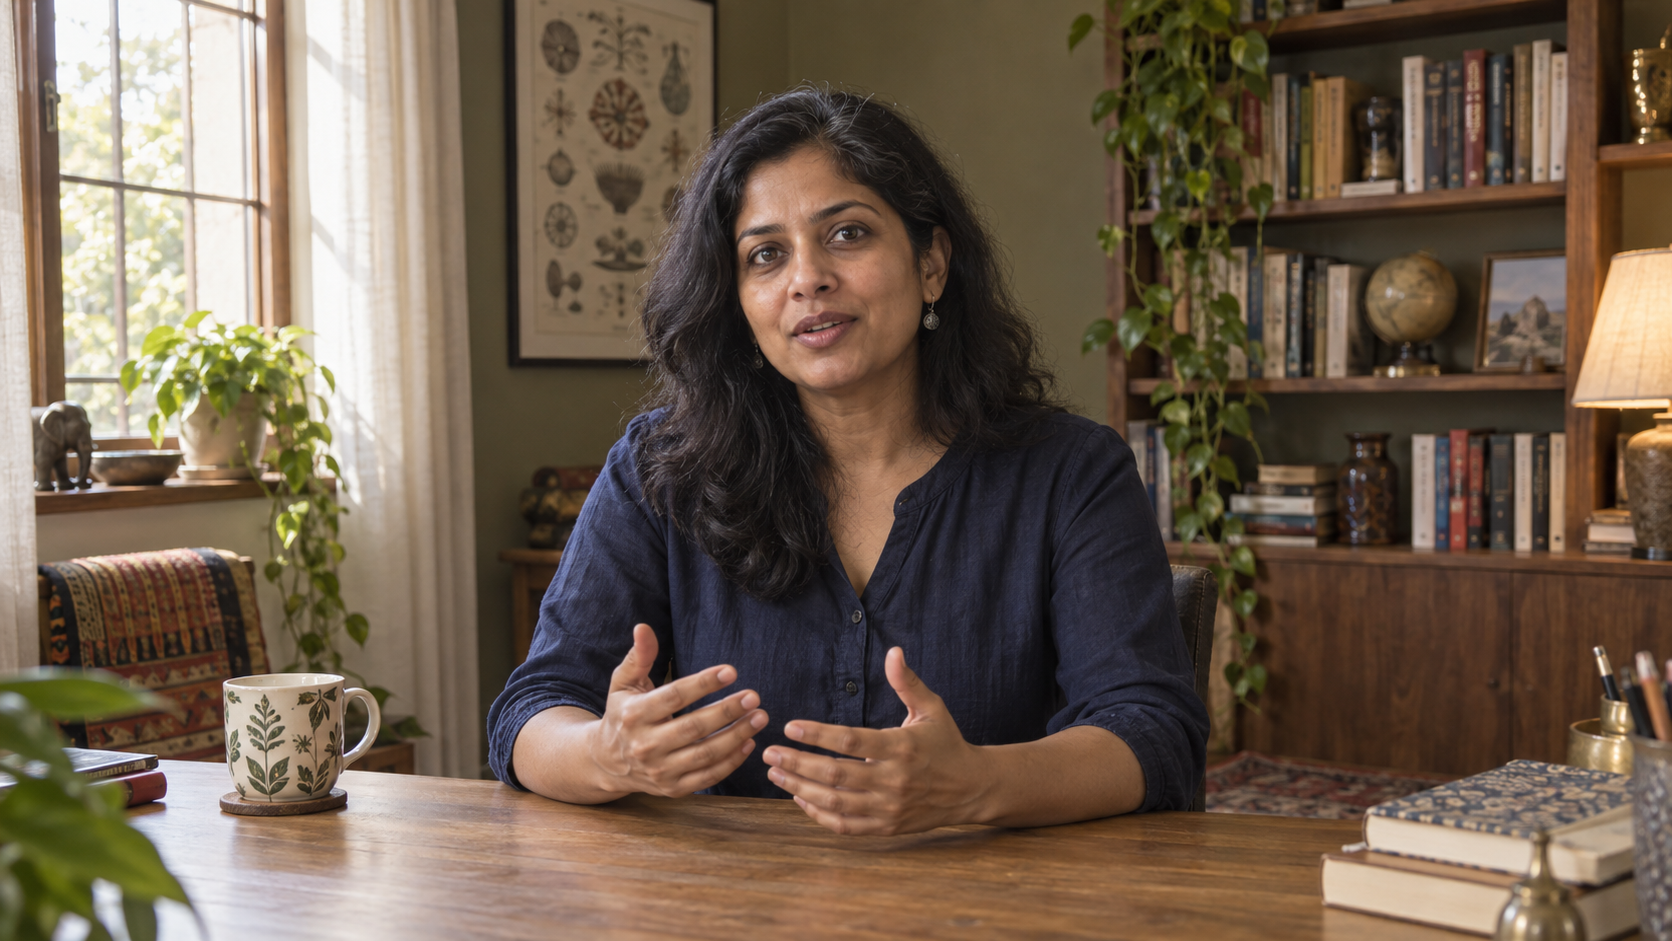
Illustrative generated still, not a MiniMax H3 result: the medium framing, visible hands, simple wardrobe, and stable background give a talking sequence more continuity evidence than a tight beauty portrait.
This segmentation also makes recovery affordable. If segment C has a weak mouth shape, rerun C instead of risking the other approved material. The same checkpoint logic in the resumable multishot workflow applies here: save the script version, reference set, prompt, output, and approved boundary frame for every segment.
Prepare the Face, Voice, Script, and Frame
Create one compact continuity packet
Choose a reference image with a readable face, relaxed lips, uncluttered background, and the same camera angle required for the finished video. A medium or medium-close frame is usually safer than a wide shot because the mouth remains large enough to inspect. Keep hair away from the lips, avoid hands crossing the lower face, and use soft directional light instead of hard moving shadows.
Write a fixed identity block and reuse it word for word. Include age range, hair, wardrobe, a distinctive but ordinary feature, vocal quality, speaking rate, accent only when important, camera height, shot size, light direction, and background anchors. Do not add new adjectives in later segments; harmless-sounding additions can change styling, age, or facial proportions.
For reference-driven generation, H3 can use image, video, and audio assets. Its official full-reference guide distinguishes visible subjects, concrete picture anchors, source videos, and audio references. When an audio reference supplies voice character rather than a copied signal, describe it as a timbre and delivery reference. Keep the same speaker ID attached to the avatar wherever she actually speaks.
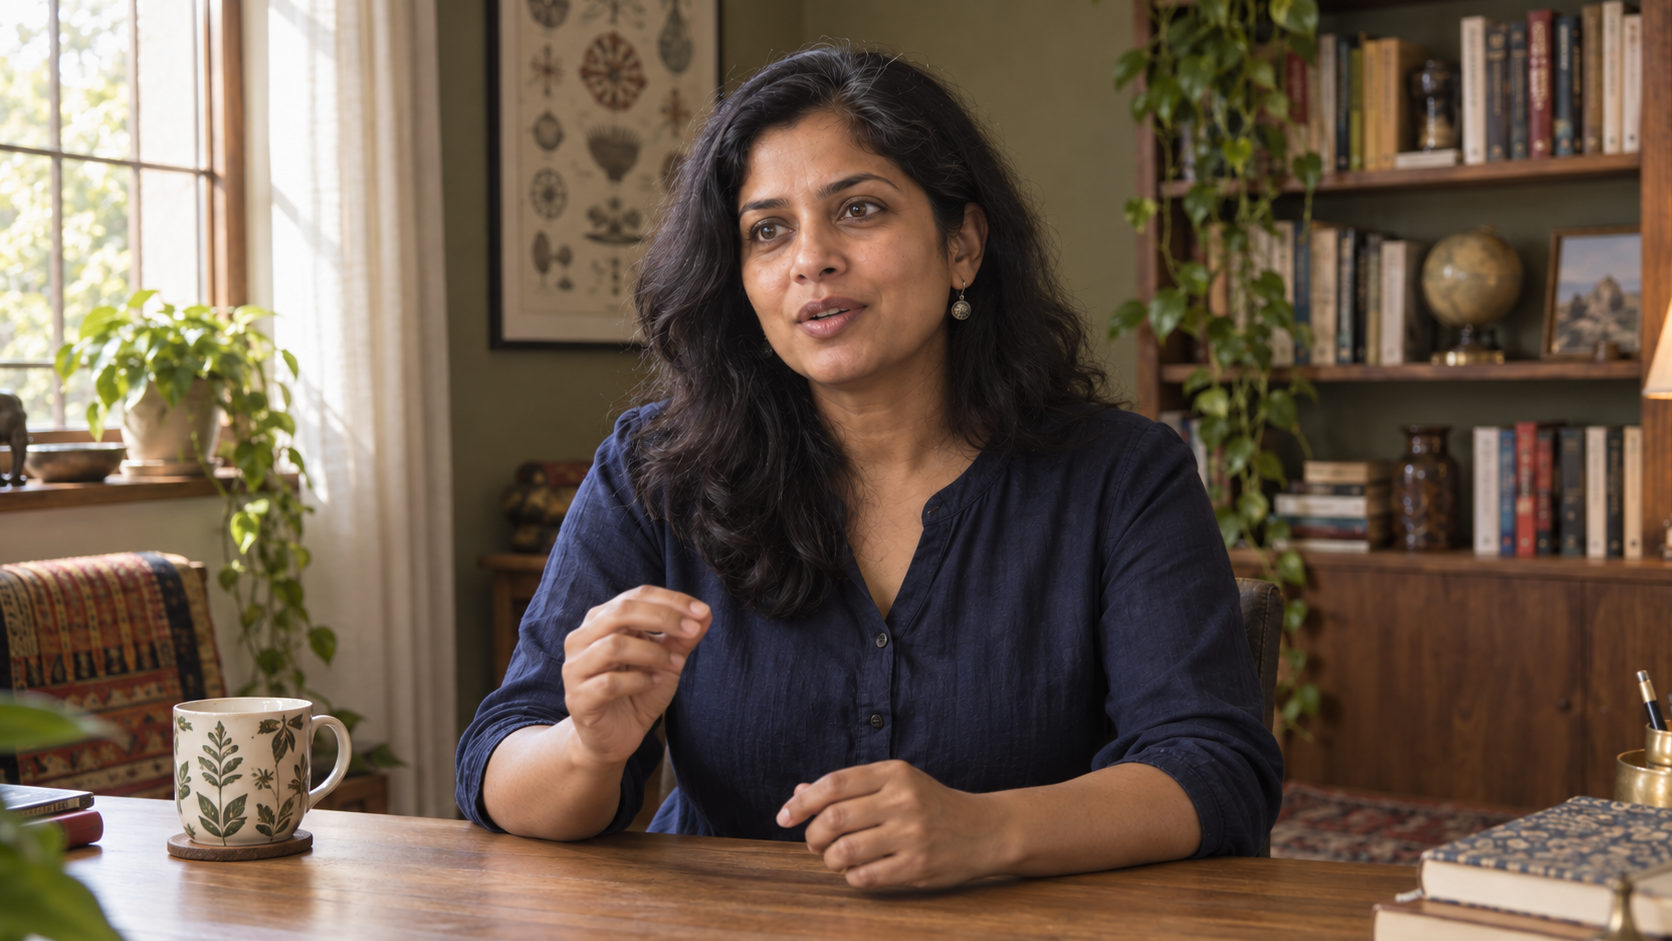
Continuity target for a speaking segment: identity, lens, eyeline, wardrobe, and light stay fixed while only the mouth shape and one small gesture change.
Record clean dialogue if you need a particular voice. Use a quiet room, consistent microphone distance, no background music, and separate files for each segment. Match loudness and room tone before generation. If the goal is simply a plausible native voice, specify stable timbre and pace but still keep the exact words in the prompt. The voice-consistency guide has a useful listening checklist that also works when reviewing H3 outputs.
Write H3 Dialogue Without Losing Speaker Identity
Keep visual direction outside the dialogue tag
The official H3 base guide uses stable speaker IDs such as (S1) and places only the words to be spoken inside <d>. The identifying phrase, action, delivery, and speaker ID remain outside the tag. That separation prevents performance notes from becoming accidental dialogue.
[Shot 1] A realistic medium shot of the same science educator seated at the oak desk. The camera, lens, light direction, wardrobe, books, plants, and cup remain unchanged. The calm adult woman (S1), with a warm low-mid voice, measured pace, and clear diction, looks just beside the lens. She makes one small open-hand gesture and says, <d>[English] A stable avatar begins with a stable handoff between every approved clip.</d> After the sentence, her lips close, her hands return to the desk, and she holds the same eyeline for one second. Quiet room tone continues. No music, no camera movement, no text overlay.
Repeat the identifying phrase when a new generation could otherwise forget who S1 is. Do not create a new speaker number for the same avatar in the next clip. If another voice enters, assign S2 once and keep the roles explicit. For a single-person explainer, excluding other audible voices removes an unnecessary source of drift.
Write one spoken clause per visible action. Fast head turns, large arm movements, camera pushes, and long sentences all compete for the same short interval. When mouth accuracy matters, hold the camera static and keep the torso quiet. Use the practical expression controls in the H3 microexpression prompt guide to ask for a restrained brow lift or nod without changing the entire face.
Carry an Anchor State Across Each Cut
End cleanly before asking for the next beginning
The final second of one clip becomes the visual contract for the next. Request a locked end state: lips together, jaw relaxed, eyes on the same mark, hands at a named position, shoulders level, and background objects unchanged. Export that approved ending as the next image anchor when the generation route allows it. A neutral hold is more reusable than a frame caught mid-word.
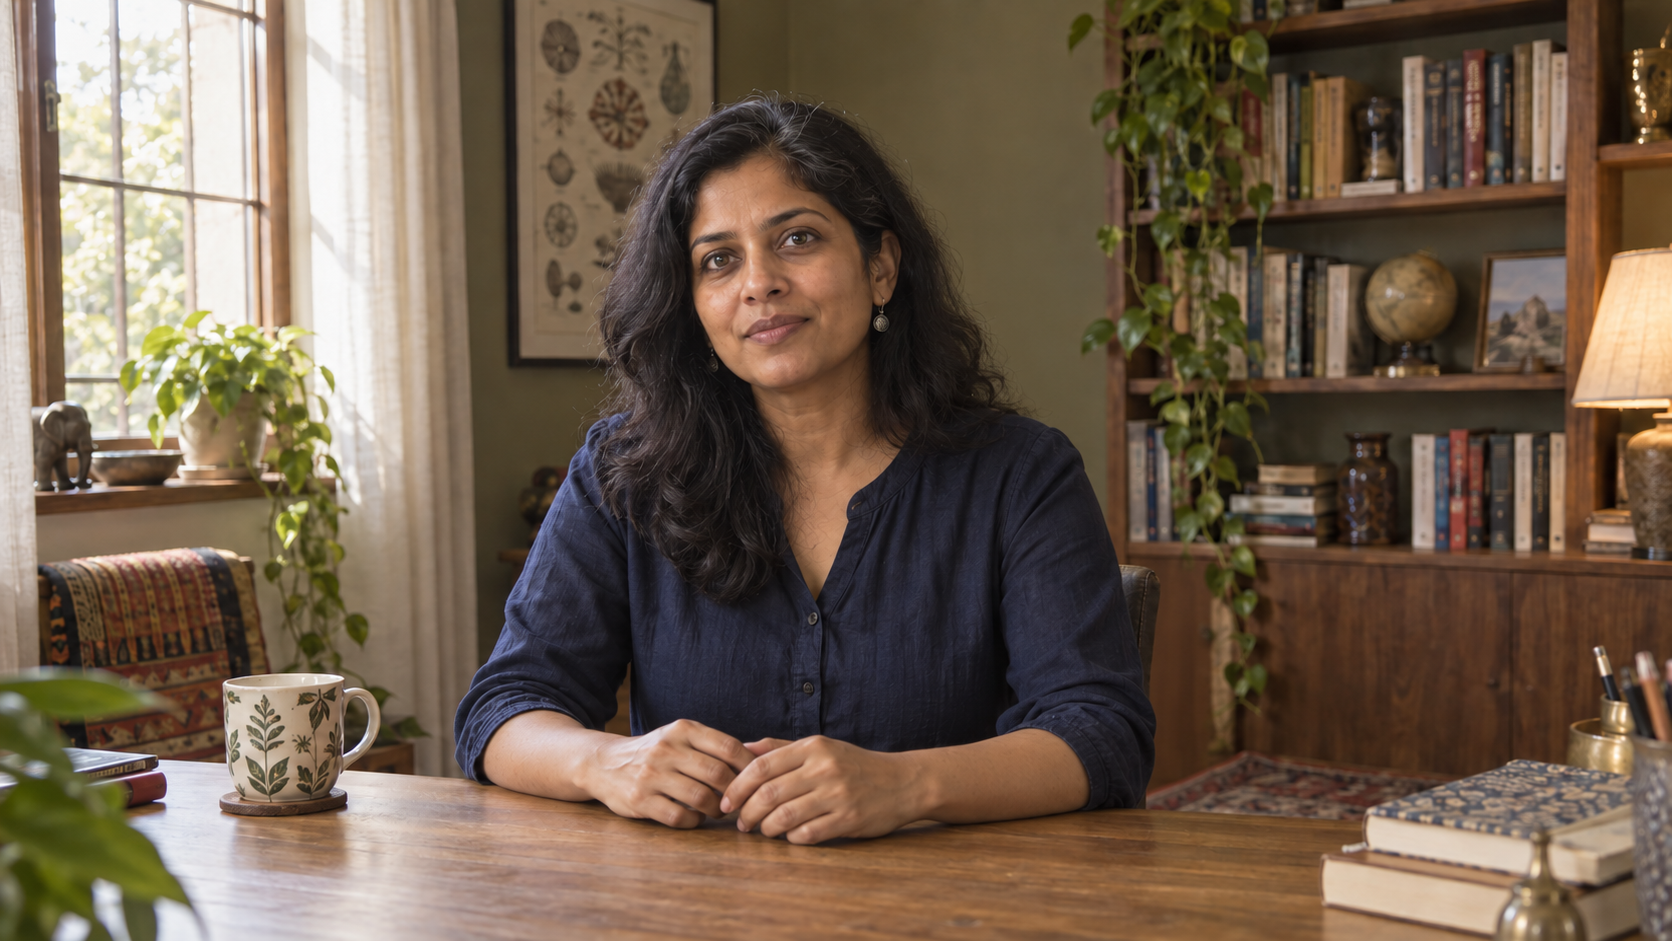
A useful boundary frame is intentionally uneventful: the mouth is closed, gaze and posture are settled, and no gesture must magically continue across the edit.
At the start of segment B, restate the locked state before the new action. Preserve head size, camera height, eyeline, light direction, sleeve position, and the location of high-contrast background objects. The first movement should begin after a brief settle, not on frame one. If the next clip opens with a different pose, the audience notices the jump before hearing the words.
H3 supports first/last-frame and reference modes, but use only the mode that matches the job. A concrete boundary image is a frame anchor; an audio sample may guide timbre; a previous video may provide motion or continuation context. More references are not automatically better. Remove any asset that contradicts the approved framing, wardrobe, or voice.
The handoff method is closely related to multi-keyframe planning, but a talking avatar needs fewer visual ambitions. One stable anchor per boundary usually beats a dense storyboard that asks the face, hands, camera, and room to change at once.
Assemble the Segments Without Audible or Visual Jumps
Cut on a pause and preserve room tone
Place every approved clip on one timeline in script order. Trim duplicate settling frames, but keep enough neutral material to move the cut away from an open mouth. Match scale and position before adding transitions. A straight cut during a natural pause is usually cleaner than a dissolve, which can briefly show two mouths and make the face look unstable.
Actual Seedance output, not a MiniMax H3 result: use this native-audio sample as a review baseline for speech timing, facial motion, and uninterrupted ambience.
Listen to the joins with the picture hidden. Match dialogue loudness, noise floor, reverberation, and the length of each breath. Lay a short continuous room-tone bed beneath the sequence so tiny gaps do not sound like the room switches off. Avoid music until the voice cut works; a soundtrack can hide a bad join during editing but will not fix it.
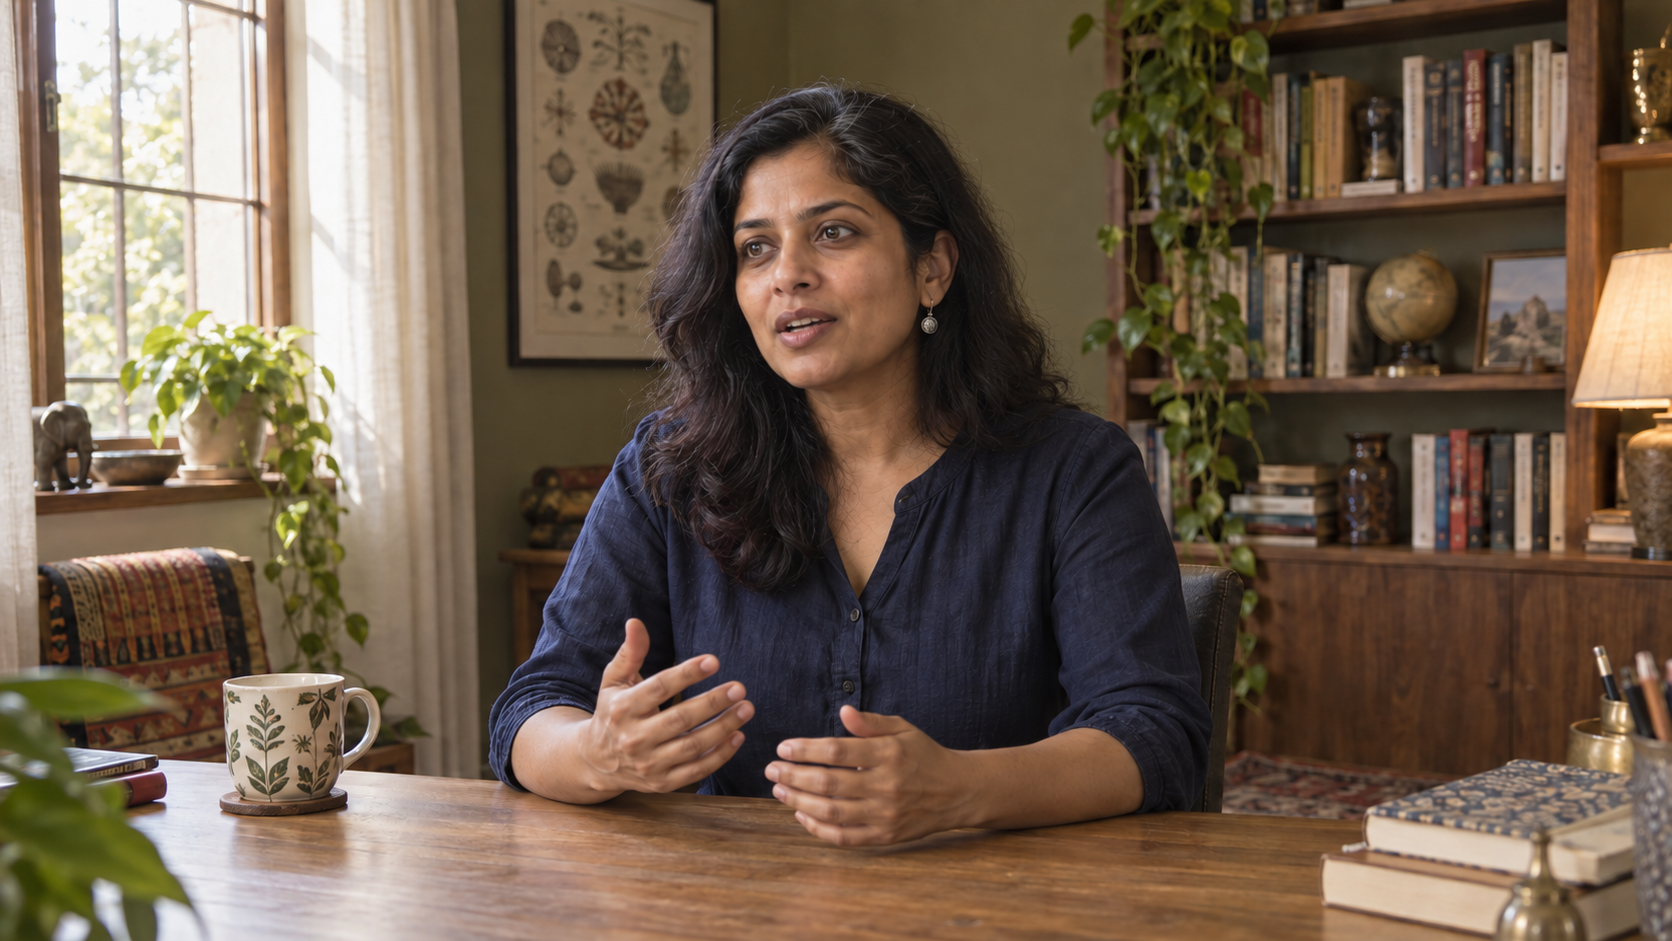
Continuation target: the identity and visual anchors remain stable while the new sentence begins with a slightly different, still believable hand gesture.
If a jump remains, use a relevant cutaway for one or two seconds: the speaker's notebook, an object she mentions, or a wider view from the same room. Do not insert random stock footage. The cutaway should answer or illustrate the spoken line and then return to the same avatar state.
Review Lip Sync, Voice, and Continuity Failures
Approve each clip on five separate passes
First watch at normal speed for meaning and natural rhythm. Second, mute the audio and inspect identity, teeth, lips, jaw, eyes, and hands. Third, listen without watching for voice timbre, pace, room tone, and clicks. Fourth, step through the opening and closing twelve frames of every segment. Fifth, watch the assembled sequence on a phone-sized player, where tiny facial changes can feel more obvious.
Reject a clip when the mouth continues after the voice stops, teeth reshape from frame to frame, the jaw slides sideways, eye color changes, a hand passes through the face, or the voice abruptly changes age or distance. Do not repair a broken identity with sharpening. Rerun the smallest failed segment from the last approved anchor.
When several failures share one cause, simplify before regenerating. Shorten the line, remove a gesture, freeze the camera, enlarge the face in frame, or replace an ambiguous reference. Seedance Agent is useful at this stage because it can keep the reference packet, segment prompts, actual outputs, notes, and approved rerun points together. You can compare H3 results with a controlled reference-to-video workflow instead of rebuilding the project from scattered files.
Conclusion
A reliable MiniMax H3 continuous talking avatar is assembled from short, reviewable speech segments: time the script, keep one identity and S1 voice definition, place exact words inside <d>, finish every clip on a neutral anchor, and join the approved takes over continuous room tone. This method does not promise infinite generation; it gives you a recoverable way to build longer explanations without sacrificing face, voice, or lip sync. To plan the references, prompts, outputs, approvals, and selective reruns in one production, start a talking-avatar project with Seedance Agent.
Ready to try it yourself?
Put the steps from this guide into practice with Seedance and turn prompts or images into polished videos in minutes.
Free credits on signup. Plans from $20/month.
Related Articles
More posts in the same locale you may want to read next.
Seedance App Preview Video Generator 2026: Create App Store and Product Launch Clips
Use Seedance to turn app screenshots, feature copy, and launch goals into App Store previews, Google Play promo videos, and product launch clips.
Read article
MiniMax H3 Camera Focal Length Control: Wide, Normal, and Telephoto Looks
Control the apparent lens look in MiniMax H3 with shot size, camera distance, zoom language, reference frames, and a repeatable 24mm-to-85mm prompt test.
Read article
MiniMax H3 Two Person Video Workflow: Keep Roles, Dialogue, and Motion Clear
Build a MiniMax H3 two-person scene with stable subject labels, readable blocking, assigned dialogue, clean prop handoffs, and a practical failure-check workflow.
Read article