
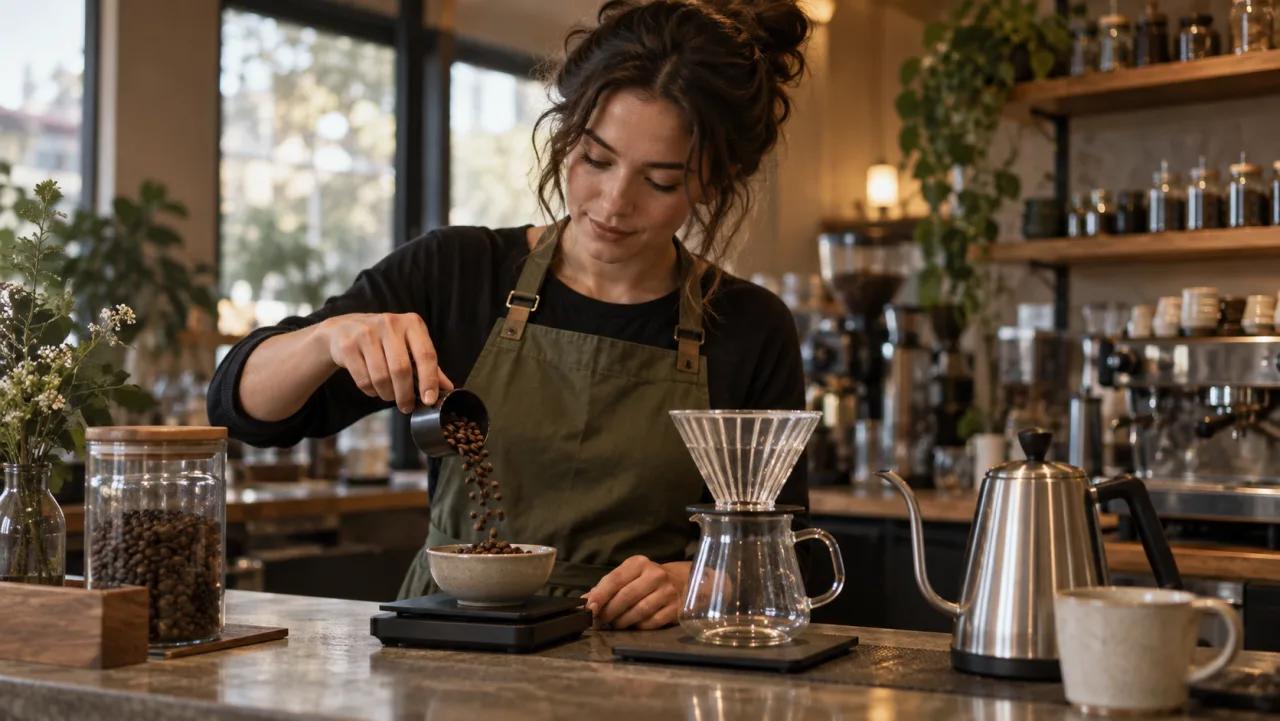
An AI video often handles one visible action well and loses the plot when a prompt asks for five. A subject may pour before picking up the kettle, an object may reset between steps, or the clip may spend its whole duration on the opening pose. The reliable fix is to turn the idea into observable state changes, give each action enough screen time, and split the sequence when one clip cannot carry it cleanly.
This guide shows how to make AI video follow a multi-step action without treating the prompt as a screenplay. The running example is a barista who measures beans, pours water, removes the dripper, and presents the finished cup. The same method applies to assembly demos, recipes, product use, craft tutorials, and short narrative beats.
AI Overview
How do I make an AI video follow steps in order?
Write each step as a visible physical action, define the state before and after it, and connect the actions with explicit order words or timestamps. Keep the sequence short enough for the clip duration.
Should a multi-step action be generated in one clip?
Use one clip for two or three tightly connected actions that fit comfortably. Split longer, delicate, or state-changing sequences into separate shots and carry the last accepted frame forward.
Why does the model skip the middle action?
The prompt may contain too many actions for the available seconds, or the middle state may be visually ambiguous. Give that step a concrete object interaction, more time, and a clear result.
How can I keep the subject and objects consistent?
Lock the reference image, wardrobe, props, camera position, lighting, and starting state. Reuse an accepted boundary frame when the next shot must begin exactly where the previous one ended.
Define Atomic Steps and States
Start with a plain-language goal, then reduce it to actions a camera can see. “Make coffee” is not an action plan. “She pours beans into the grinder” is. Avoid combining intention, emotion, camera movement, and several object changes in one sentence. Each line should have one actor, one verb, one object, and one visible result.
Create a state-transition worksheet before writing the prompt:
| Step | Start state | Visible action | End state | Continuity lock |
|---|---|---|---|---|
| 1 | Beans in scoop; grinder empty | Barista pours beans into grinder | Scoop empty; beans in grinder | Same apron, counter, cup |
| 2 | Kettle raised; dry coffee bed | Barista pours in a slow circle | Coffee bed blooming | Same hand, kettle, camera |
| 3 | Pour complete; dripper on carafe | Barista sets kettle down and lifts dripper | Filled cup ready | Liquid level and prop positions |
| 4 | Cup on counter | Barista slides cup forward | Finished cup presented | Same light and background |
The end state matters as much as the action. It tells the generator what must remain when the next action begins. If a plate, tool, garment, or product changes orientation, write that result down. This discipline also improves a simple text-to-video workflow, because the prompt describes evidence rather than a vague intention.
Fit Actions to the Available Duration
A sequence fails when its action budget exceeds its time budget. Allow time for anticipation, execution, and settling. A hand must reach the kettle before pouring; the kettle must stop before it is set down. Those transition beats are short, but they prevent teleportation.
For a five-second clip, aim for one main action or two simple connected actions. In eight to ten seconds, two or three actions may work if the camera stays stable and the objects remain easy to read. Four deliberate steps usually deserve multiple shots. Fast montage timing can show more events, but it does not prove that one continuous action was completed.
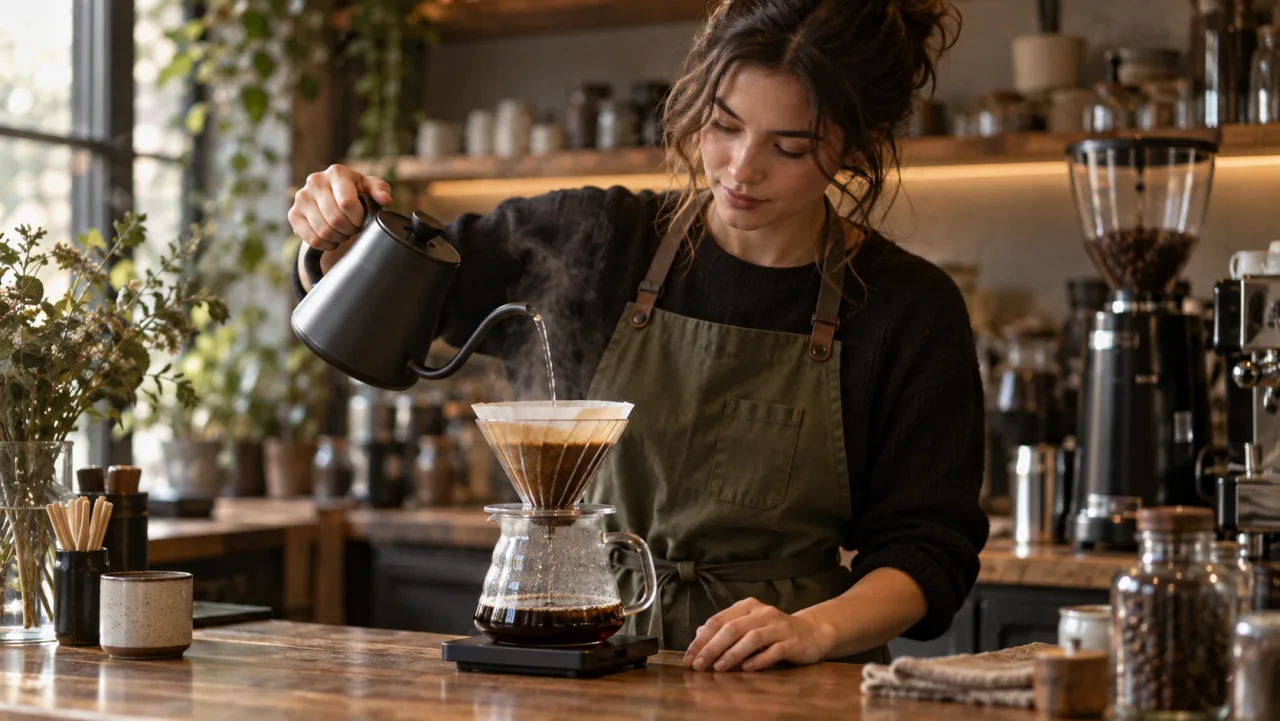
Assign rough windows only after simplifying the sequence. For example: 0–2 seconds, lift the kettle; 2–6 seconds, pour in a slow circle; 6–8 seconds, return the kettle to the counter. Leave a clean resting state at the end. Exact timestamps are guidance, not frame-accurate editing commands, so evaluate the visible order rather than the numbers.
If duration is fixed, remove decorative motion first. A camera orbit, drifting steam, background patrons, and a complex hand action all compete for motion capacity. Keep the camera locked for the first successful take, then add a restrained push-in after the action order is stable.
Build a Sequential Action Prompt
Describe the stable scene once, then the ordered actions, then the camera and quality constraints. This keeps the prompt readable and prevents a long style preamble from hiding the task.
Use this copy-ready template:
[Subject and fixed appearance] in [stable environment].
Starting state: [positions of hands, tools, and objects].
First, [one visible action and result].
Then, [one visible action and result].
Finally, [one visible action and final resting state].
The actions occur in this exact order with natural hand contact and no object resets.
[Camera framing and movement]. [Lighting and visual style].
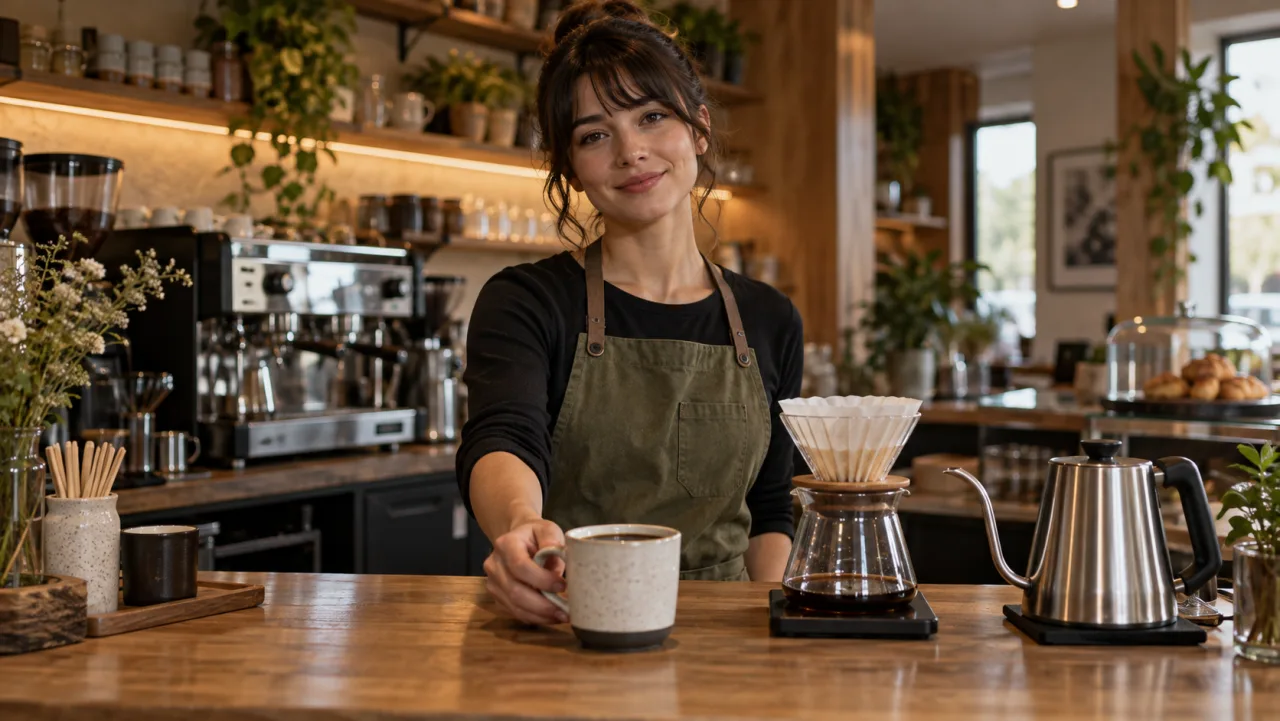
For the coffee shot: “A barista in an olive apron stands behind a wooden coffee bar. Starting state: her right hand holds a gooseneck kettle above a dry coffee bed. First, she begins a slow circular pour. Then, the coffee blooms while she continues the controlled circle. Finally, she stops pouring and places the kettle on the counter. The actions occur in this exact order. Locked medium shot, warm natural window light.”
Positive descriptions usually work better than a long list of prohibitions. State “the cup remains on the left side of the carafe” rather than relying only on “do not move the cup.” If the starting composition is important, begin with image-to-video and choose a reference that already contains every essential prop.
Generate One Shot or Split into Clips
Generate a single shot when the same subject performs a continuous action in one location and the camera can observe every result. Split the sequence when an object transforms, the subject changes position, a new tool enters, or one step repeatedly disappears.
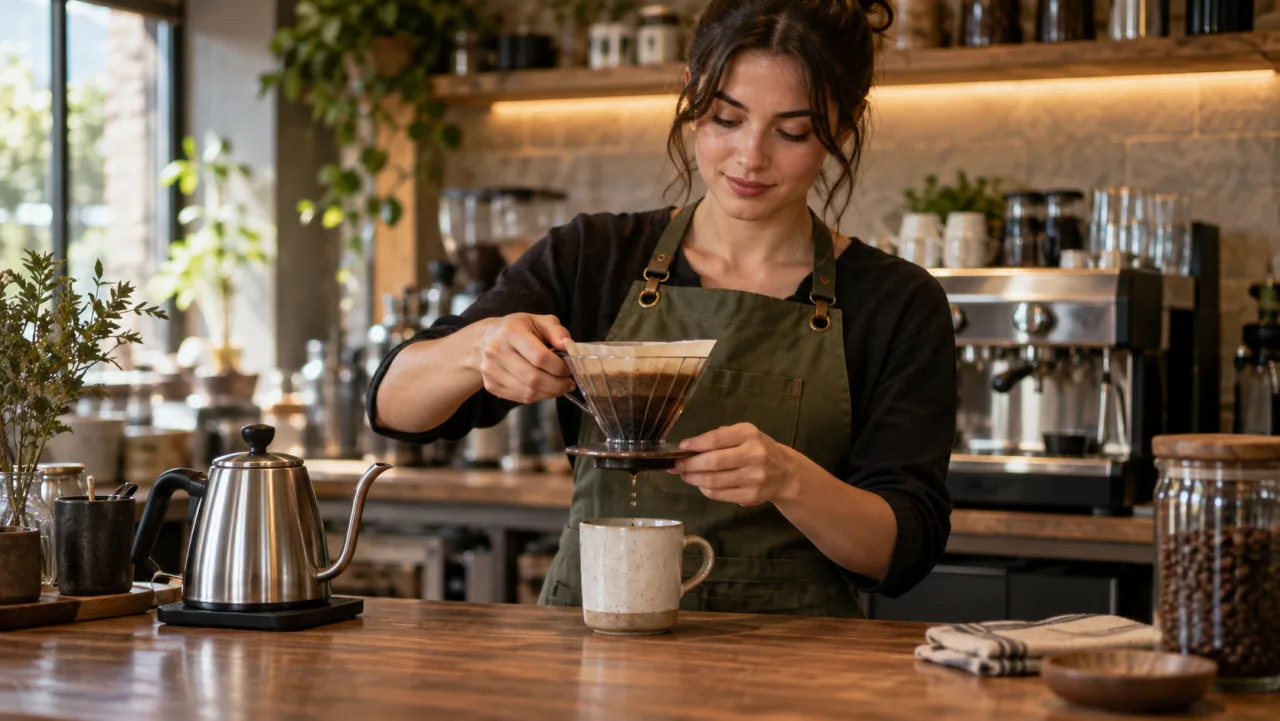
A practical decision rule is simple: if you cannot describe the sequence with three verbs and one stable starting image, use more than one shot. Shot one can end with the kettle resting on the counter. Shot two begins from that accepted end frame and shows the dripper being removed. This gives each generation a smaller job while preserving the appearance of one workflow.
Do not keep rerolling an overloaded prompt. After two or three failures with the same missing step, shorten the unit. The Pika multiple-keyframe tutorial is useful when a tool supports explicit visual waypoints. For broader identity and environment control, use the methods in the AI video consistency guide.
Carry Continuity Between Steps
The boundary between clips is where multi-step workflows often break. Save the last frame only after the hands, props, and subject are in a neutral readable state. A frame with motion blur, a half-hidden tool, or fingers crossing an object gives the next generation uncertain geometry.
Carry five locks into the next shot: subject identity, wardrobe, hero object, environment, and camera direction. Also note the variable that is allowed to change. In the coffee example, the liquid level may rise, but the cup design, apron, countertop, and light direction must remain fixed.
When using a boundary frame, describe it as the starting state instead of repeating the whole previous action. The next prompt should say, “The kettle rests on the right side of the counter and the filled dripper remains above the carafe. The barista lifts the dripper straight up.” Replaying the pour invites the model to restart it.
This real Seedance example is included as an independent motion reference for judging contact, camera stability, and settling. It is not evidence that this exact coffee sequence was generated in one pass.
Review and Repair the Sequence
Watch at normal speed first. Confirm the actions occur in order and that each produces its required state. Then inspect frame by frame around hand contact and shot boundaries. A beautiful take still fails if the lid opens before the hand touches it or a filled container becomes empty.
Use a compact acceptance checklist:
- Every required action appears once and in order.
- The starting and ending states are visually readable.
- Hands contact the intended object without merging or switching sides.
- Props do not vanish, duplicate, reset, or change design.
- Camera direction and subject screen position remain consistent.
- The final frame can serve as a clean handoff or edit point.
Repair the smallest faulty unit. If step two is absent, allocate it more time or isolate it in a new shot. If identity drifts, strengthen the reference and reduce camera motion. If the object transforms, choose a clearer boundary frame and restate its geometry. If the edit feels abrupt, add a half-second settling pose rather than regenerating the whole sequence.
Seedance Agent is useful when the job needs several generations: it can keep the state worksheet, references, shot order, review notes, and targeted reruns together. That makes approval about observable transitions instead of asking whether an attractive clip “feels right.”
Conclusion
To make AI video follow a multi-step action, convert the idea into atomic verbs, define every start and end state, budget the actions against the clip length, and split the sequence before it becomes overloaded. Preserve continuity with clean boundary frames, stable visual locks, and a review checklist that tests order rather than style alone. When you are ready to plan, generate, compare, and repair a longer action chain, build the workflow in Seedance Agent.
Ready to try it yourself?
Put the steps from this guide into practice with Seedance and turn prompts or images into polished videos in minutes.
Free credits on signup. Plans from $28/month.
Related Articles
More posts in the same locale you may want to read next.
Seedance App Preview Video Generator 2026: Create App Store and Product Launch Clips
Use Seedance to turn app screenshots, feature copy, and launch goals into App Store previews, Google Play promo videos, and product launch clips.
Read article
Pictory Edit Video Using Text: Cut a Recording From Its Transcript
Upload a recording to Pictory, verify its transcript, delete text to cut video, repair jump cuts and captions, add B-roll, and export a clean final version.
Read article
ElevenLabs Voice Changer Video Tutorial: Replace a Voice and Keep the Performance
Transform a video's dialogue with ElevenLabs Voice Changer, preserve emotion and timing, restore lip sync, troubleshoot artifacts, and finish a consistent mix.
Read article