
FramePack 6GB VRAM Setup Guide: Install, Test, and Tune Safely
AI Overview
Can FramePack really run on 6GB VRAM?
Yes, the official project lists 6GB as the minimum for supported NVIDIA RTX 30-, 40-, and 50-series GPUs. It is a minimum working target, not a promise of fast generation.
What is the safest FramePack installation for Windows?
Use the official one-click package, extract it to a simple local path, run update.bat, then run.bat. Leave the default attention and TeaCache settings for the first test.
How do you fix CUDA out-of-memory errors in FramePack?
Close other GPU apps, restart the process, test the default workflow, and reduce competing system-memory pressure. Add one optimization at a time so its effect remains measurable.
Should TeaCache be enabled on a 6GB GPU?
Use TeaCache for faster drafts only after a clean default render succeeds. The official guidance warns that it can reduce quality, so use full diffusion for important final output.
What 6GB support really means
FramePack is designed to generate long videos without letting the working memory grow with video length. Its frame-context packing and anti-drift scheduling keep the active computation bounded while the model streams forward. That design is why the official project can demonstrate a 13B model producing video on an RTX 3060 laptop with 6GB VRAM. It does not make every part of the workflow lightweight: the model files still need more than 30GB of disk space, system RAM and virtual memory can become busy, and a long generation can take substantial time.
The supported baseline is also specific. The official README names Windows or Linux with an NVIDIA RTX 30-, 40-, or 50-series GPU that supports fp16 and bf16. GTX 10- and 20-series cards are explicitly described as untested. Six gigabytes of VRAM is not the same as six gigabytes of system RAM, and meeting the minimum does not guarantee that experimental quantization, third-party nodes, every attention kernel, or aggressive cache settings will work together.
Treat this FramePack 6GB VRAM setup guide as a controlled route to one known-good render. First prove that the official application, model and default settings work. Then measure one change at a time so a failure can be traced to the GPU limit, environment or optimization.
Illustrative source-frame concept, not a FramePack benchmark. A clear subject, readable silhouette and uncluttered background make a better first 6GB test than a crowded action scene.
Prepare Windows or Linux
Run a six-point preflight
Before downloading, confirm six things: a supported NVIDIA RTX GPU with at least 6GB VRAM; a current driver; enough free disk for the package, dependencies and more than 30GB of automatic model downloads; a short local install path; stable network access; and permission to create files in that folder. On a minimum-memory machine, close games, 3D software, browser tabs using GPU acceleration and other local AI servers before the first launch.
Keep the input modest. Choose one clean still with one primary person or object, a simple background and a motion that can be described in one sentence. The first run is an environment check, not the final creative brief. If you are deciding whether the local setup is worth maintaining, compare the complete effort with a cloud GPU benchmark, not only the advertised VRAM number.
For Windows, the official one-click package already pairs CUDA 12.6 with PyTorch 2.6. Avoid adding a second Python environment inside it before the baseline works. For Linux, use an independent Python 3.10 environment so an existing ComfyUI or system Python cannot silently replace packages. The same isolation principle appears in this local AI video setup guide. Record the driver version, install folder and free disk space; those three details are far more useful in a later bug report than “it stopped.”
Install FramePack from the official source
Windows one-click route
Download only from the repository identified by the developers as the official FramePack project. The project warns about imitation sites, so verify the repository owner before running any package. Extract the archive completely to a short path such as D:\\FramePack; running from inside a compressed archive or a deeply nested cloud-synced folder adds avoidable file and permission problems.
Run update.bat once, allow it to finish, and then run run.bat. The first launch can look idle while large model files download and initialize. Watch the terminal rather than refreshing the browser repeatedly. Do not interrupt merely because the progress bar pauses during warmup. If an update later breaks a working installation, keep the last known-good folder until the new copy passes the same sanity check.
Linux environment route
Create a clean Python 3.10 environment, activate it, install the CUDA 12.6 PyTorch packages from the official PyTorch index, install FramePack requirements, and then start python demo_gradio.py. Keep the environment dedicated to FramePack. Mixing it with a large ComfyUI environment can leave mutually incompatible Torch, Triton or attention packages even when pip reports a successful install.
The default path uses PyTorch attention. FramePack also supports xformers, FlashAttention and SageAttention, but support is not an instruction to install all of them. Begin with the default because it is the cleanest reference point. A similar discipline helps when comparing INT8 and INT4 encoder choices: a smaller footprint is useful only if the final output still passes review.
Illustrative first-frame candidate. Preserve this image, prompt, seed and settings before changing the environment so each test has a stable visual reference.
Run the 6GB sanity check
Freeze the variables
Use the official defaults, keep TeaCache off, and avoid SageAttention, bits-and-bytes quantization or GGUF for the first render. The project calls this default configuration the sanity check. Load the prepared image and write a concise motion prompt that prioritizes subject and movement, for example: “A ceramic artist slowly turns the cobalt vase clockwise, checks the glaze in window light, and stops with both hands steady; the camera remains locked.”
Save a small test record with four columns: build and environment, input and prompt, changed setting, and result. The first row should say “official defaults; no change.” Pass the run only if the app loads the model, begins sampling, completes a playable file and preserves the basic subject. Speed is secondary. On a 6GB card, successful but slow is evidence that the environment works; an instant crash is not evidence that the model is impossible.
Warmup can make the beginning appear slower than later sections. Let the terminal reach an explicit completion or error before diagnosing it. Replay the whole output and look for subject drift, scene replacement, stuck motion or a damaged final second. A weak playable file is a creative result; a CUDA exception is a system failure.
This is an actual FramePack output from the official project page, not a Seedance render or a speed guarantee. Its purpose is to prove the published 6GB route can produce continuous motion.
Tune speed without hiding failures
Use a draft-to-final ladder
Once the default run passes, create a three-step ladder. Step one is the untouched quality reference. Step two enables one speed feature, such as TeaCache, for idea exploration. Step three returns to full diffusion for the selected final take. Compare the same input, prompt and approximate length at each step. Record wall time, peak VRAM if available, visual defects and whether the result is acceptable—not just whether it is faster.
The official guidance says TeaCache may worsen results for some users and recommends it for trying ideas rather than final quality. It gives the same caution for SageAttention, bits-and-bytes quantization and GGUF. These options can be valuable, but stacking them removes your control: if hands deform or textures pulse, you will not know which shortcut caused it. Add one, render once, and roll back when the saved reference looks better.
Illustrative motion target. Compare the vase shape, face, hands and studio lines against the saved first frame; speed is not a win if those anchors drift.
Prompt economy also matters. FramePack’s own advice favors compact, motion-focused language. Name the subject, the main action and one camera behavior. Avoid a paragraph of conflicting lens changes, costume transformations and scene cuts. If you need multiple distinct shots, plan and approve them separately through an image-to-video workflow, then edit the results. One generation should solve one visible beat.
Troubleshoot low-VRAM problems
Follow the failure, not a random checklist
If the app never opens, inspect the first terminal error for a missing package, unsupported GPU or corrupted download. Re-run the official updater or reinstall in a clean folder instead of patching several libraries blindly. If the model begins loading and then fails, check free disk, system-memory pressure and page-file or swap availability; close competing processes and restart the machine before changing the model. If sampling starts and then throws CUDA out of memory, confirm that another GPU process is not holding memory and repeat the official default test.
If only an optional kernel fails, remove that kernel and return to PyTorch attention. An optimization that cannot run on the current driver and GPU is not required for FramePack itself. If the interface freezes after a completed generation, separate that symptom from CUDA memory and follow a post-generation freeze diagnosis. Capture the full terminal message, not just the last line, and keep the input plus settings that reproduce it.
For slow but successful runs, decide whether time is actually blocking delivery. A 6GB local GPU may be appropriate for overnight exploration while a hosted workflow is better for a deadline, collaboration or many variants. Seedance Agent offers another production route: organize references, plan shots, review real outputs and rerun only the failed part without maintaining a local dependency stack. That is not a claim that one model replaces FramePack; it is a comparison between owning the environment and buying a managed workflow.
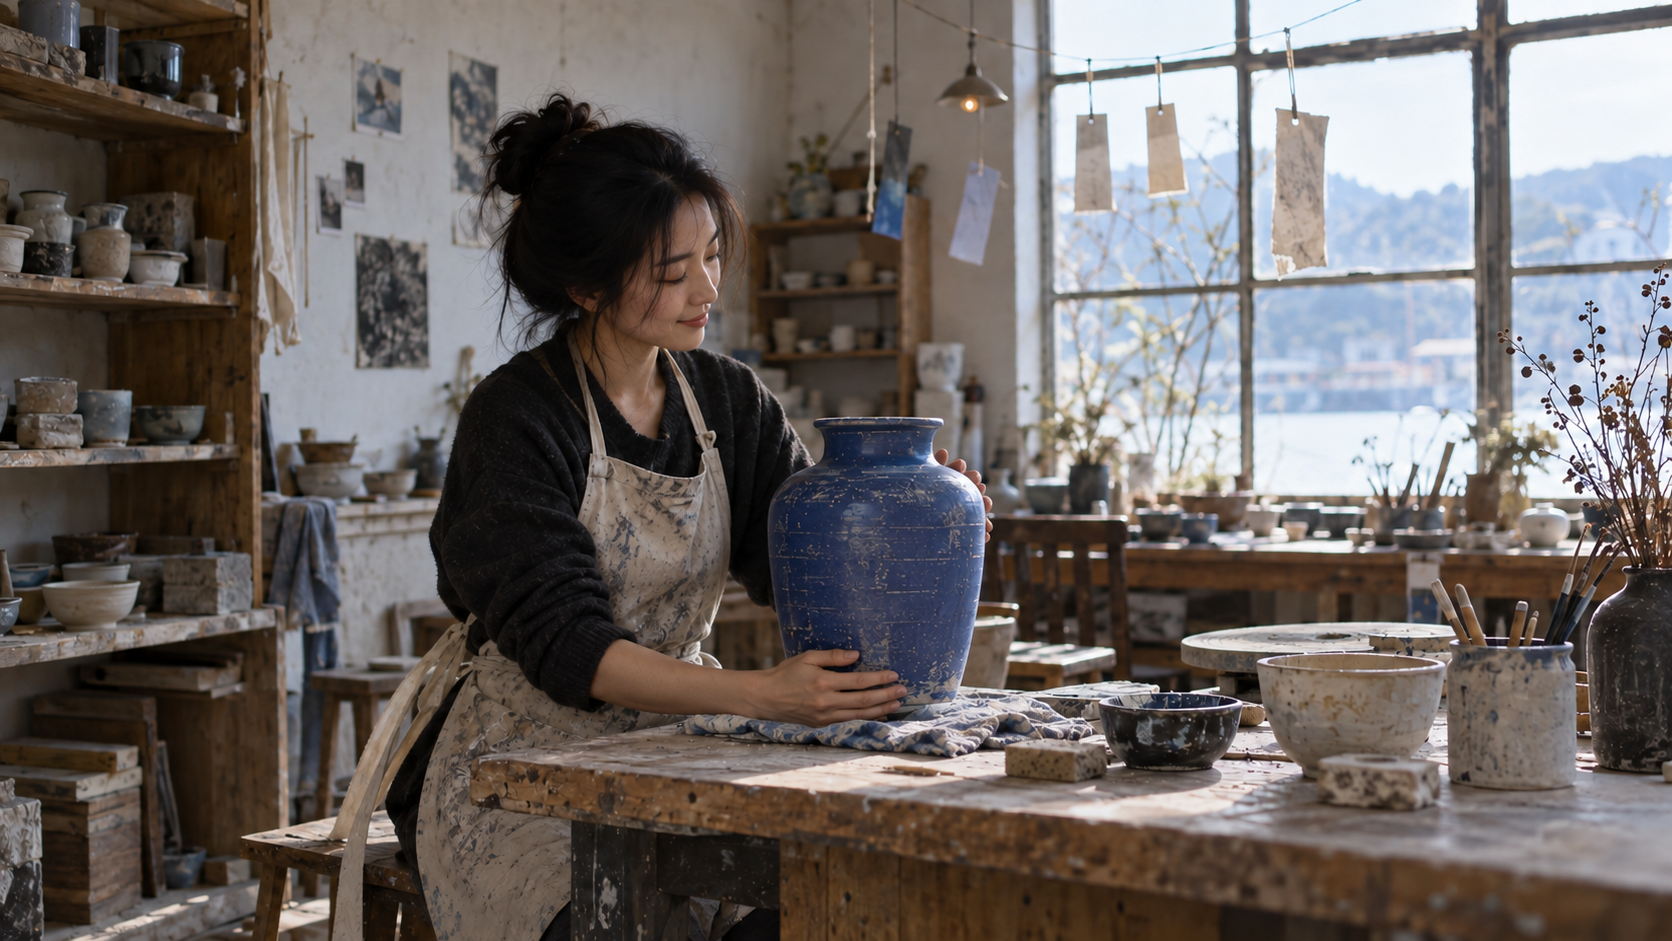
Illustrative final approval frame. Compare it with the start for identity, vase geometry, lighting and background continuity before calling the run complete.
Conclusion
A reliable FramePack 6GB VRAM setup starts with the official package, a supported RTX GPU, enough disk and system memory, one simple source image, default PyTorch attention and TeaCache turned off. Prove that baseline before adding a cache, alternate attention kernel or quantization; measure each change against the same saved input and full-video review. Six gigabytes can be a workable minimum, but the real decision is whether local generation time and dependency maintenance fit the project. If you would rather plan the shots, control references and review outputs in one managed path, start the next video with Seedance Agent.
Ready to try it yourself?
Put the steps from this guide into practice with Seedance and turn prompts or images into polished videos in minutes.
Free credits on signup. Plans from $20/month.
Related Articles
More posts in the same locale you may want to read next.
Seedance App Preview Video Generator 2026: Create App Store and Product Launch Clips
Use Seedance to turn app screenshots, feature copy, and launch goals into App Store previews, Google Play promo videos, and product launch clips.
Read article
Google Vids Slides to Video: Convert a Deck into a Publishable Video
Convert Google Slides into Google Vids scenes, use speaker notes and optional Gemini narration, replace static slides with motion, and export a publishable work video.
Read article
MiniMax H3 Plastic Skin Fix for Video Ads: A Realism Workflow
Fix plastic-looking skin in MiniMax H3 video ads with better references, natural lighting, controlled prompts, motion review, and a clear regenerate-or-finish checklist.
Read article